What Is RAG, and Why the Data Layer Decides Everything

- LAST UPDATED
- 17 min read
Key takeaways
- Most “hallucinations” are retrieval failures. In 70 percent of the engagements Mactores reviewed, the correct passage was never retrieved.
- Pipeline quality decides accuracy. Well-tuned RAG scores 65 percent on factual questions, compared with 46 percent for unoptimised pipelines.
- Each retrieval layer compounds. Contextual chunks cut retrieval failures by about 35 percent, adding keyword search raised that to 49 percent, and reranking took it to 67 percent.
- RAG costs far less than long context at scale. One head-to-head found a million-token context window cost about 24 times more than a retrieval pipeline.
- Facts that change more than once a week belong in retrieval. Stable behaviour belongs in fine-tuning, and live data such as balances or ticket status belongs behind a tool call.
Definition
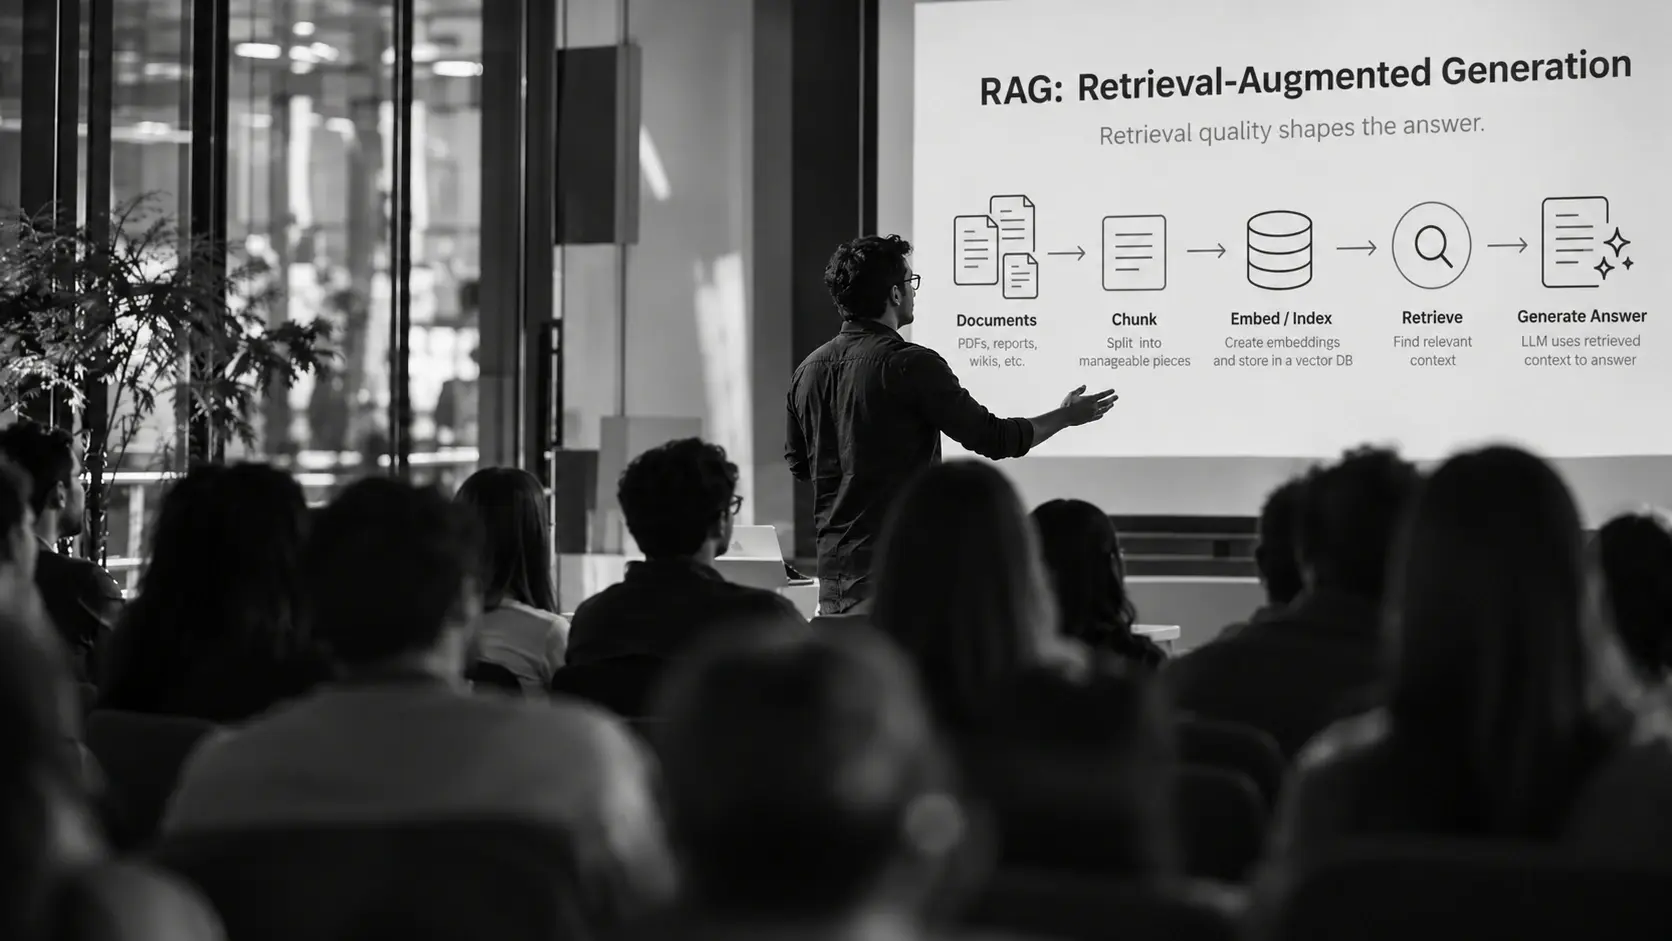
RAG (retrieval-augmented generation) is a pattern that searches an organisation’s own content when a question is asked and places the most relevant passages into the model’s context window before it writes an answer. The model supplies fluency and reasoning, and the retrieved data supplies the facts.
Ask ten teams a simple question ‘What is RAG?’ and you will get ten answers pitched at ten different altitudes. Here is the one that survives contact with production. RAG, or retrieval-augmented generation, is a pattern that searches your own content at question time and places the passages it finds into the model’s context window before the model writes a single word. The model supplies fluency and reasoning. Your data supplies the facts.
That division of labour is the whole idea, and it is also where the trouble starts. Almost every disappointing deployment traces back to the retrieval half of the pattern, and almost every remedy that teams try first sits in the generation half.
This guide stays away from product names. It covers how the pattern works, what it competes with, where it breaks, and what the data layer has to look like before any of it holds up.
Introducing RAG in simple words
A RAG system runs four stages every time somebody asks a question. Three of them happen before the model is involved.
How a RAG pipeline works: the four stages
| Dimension | Data migration | What a failure here looks like |
|---|---|---|
| Ingest and chunk | Documents are parsed, split into passages and enriched with metadata | The answer exists in your corpus and never reaches the model |
| Embed and index | Passages become vectors, usually alongside a keyword index and a metadata index | Semantically similar text outranks the exactly correct passage |
| Retrieve and rerank | The query pulls candidate passages, then a second pass scores them for relevance | The right passage sits at rank 40 and the model sees the top 10 |
| Ground and generate | Retrieved text enters the prompt and the model composes an answer | A fluent, confident answer built on the wrong passage |
Why RAG is a search problem before it is a model problem
Retrieval-augmented generation is a search system with a language model attached to the end. Everything the field already knows about search applies: recall matters more than elegance, keyword matching still beats embeddings on names and identifiers, and relevance is a property of the corpus rather than the algorithm. Teams staffed entirely with ML engineers and no search background tend to learn this the expensive way.
RAG vs fine-tuning vs long context: how to choose
Comparing the four approaches
| Approach | Best at | Where it breaks down | Cost shape |
|---|---|---|---|
| RAG |
Facts that change, large private corpora, answers that must cite a source |
Retrieval quality caps everything downstream of it |
Indexing cost up front, small cost per query |
| Fine-tuning | Tone, format, house style, narrow reasoning patterns |
Facts go stale the moment training stops |
Training cost per iteration, cheap inference |
| Long context |
Corpora small enough to fit, questions that need whole-document reasoning |
Cost and latency scale with every token on every call | Highest cost per query |
| Direct tool calls |
Live operational state such as balances, tickets, inventory |
Requires a real API and clean authorisation |
Cost per call, plus the integration build |
One published head-to-head fed the same documents through all three of the first approaches and found the million-token context window cost roughly twenty-four times what the retrieval pipeline cost at scale.
The economics explain why RAG survived the arrival of long context windows, and why most 2026 architectures use both: fine-tuning for stable behaviour, retrieval for current facts, and a routing step that decides per query whether retrieval alone is enough.
The update-frequency rule
The practical rule is about how often facts move. Facts that change more often than once a week belong in retrieval. Behaviour that should never change belongs in the weights. Anything genuinely live, such as an account balance or a ticket status, belongs behind a tool call rather than an index.
How RAG behaves in production
Gartner predicts that over 40 percent of agentic AI projects will be cancelled by the end of 2027, citing escalating costs, unclear business value and inadequate risk controls. Retrieval quality sits underneath all three. A system that returns the wrong passages burns tokens on noise, produces answers nobody trusts enough to act on, and cannot demonstrate to a reviewer which evidence it used.
Public benchmark work points the same way. Our experts put well-tuned RAG at 65 percent on factual questions and unoptimised pipelines at 46 percent. Those numbers embarrass demos, and they match what teams find when they finally instrument retrieval rather than eyeballing answers.
Our own engagement reviews put a sharper point on it.
“Across the retrieval engagements we reviewed in 2024 and 2025, plenty of them arrived with the same diagnosis from the customer: the model is hallucinating. Once we instrumented retrieval before touching a single prompt, 70 percent of those turned out to be cases where the correct passage had never been retrieved at all. The model was answering the question it was actually given. We now measure recall before we read a prompt, and it has changed the first two weeks of every engagement since.”
The practical takeaway holds even without the numbers. When an answer is wrong, check what the model was given before you change how it was asked. Prompt engineering applied to a retrieval failure produces weeks of movement and no improvement.
Chunking strategy sets the retrieval ceiling
Splitting documents on a fixed token count severs paragraphs, separates a question from its answer, and discards the structure that made the document readable. No embedding model and no reranker recovers information that the chunker destroyed.
Chunk boundaries deserve the attention teams usually spend on model selection, and structure-aware splitting on headings, sections and table boundaries outperforms fixed windows on almost every corpus.
Why vector search alone under-retrieves
Dense vectors capture meaning and lose precision on exactly the tokens enterprises care about: part numbers, policy codes, customer names, error strings, version identifiers. Keyword search handles those cases well and has for decades. Running both and merging the results is the production standard for good reason.
What reranking can and cannot fix
Cross-encoder reranking is a genuine improvement, and it operates strictly on the candidates the first stage produced. If the correct passage never entered the top 30, no amount of second-pass scoring will surface it. Reranking improves precision, and first-stage recall remains the binding limit.
Anthropic’s published work on contextual retrieval illustrates how these layers compound. Prepending explanatory context to each chunk before embedding cut top-20 retrieval failures by roughly 35 percent on its own.
Combined with keyword search the reduction reached about 49 percent, and adding reranking brought it to roughly 67 percent. Each layer helped, and the largest single gain came from fixing the chunks.
Why the data layer decides RAG accuracy
Once retrieval is instrumented, the remaining problems stop looking like machine learning problems and start looking like data engineering problems. McKinsey’s global State of AI survey finds inaccuracy the most commonly experienced negative consequence of AI use, with roughly three-quarters of respondents rating it a highly relevant risk. In a retrieval system, most of that inaccuracy is manufactured upstream of the model, in five properties of the corpus.
Index freshness: how stale can an answer be?
An index is a cache, and every cache goes stale. Decide the acceptable staleness window per source before you build, because the answer determines your architecture. Fifteen minutes means streaming ingestion and incremental updates.
Overnight means a batch job. A quarter means almost anything works. Teams that skip this decision discover it later as a support ticket about an answer quoting a superseded policy.
Metadata and document structure
Every passage should carry the source system it came from, the document version, the effective date, the owning team, and whatever classification the business already applies.
Metadata does three jobs at once: it filters the search space before the vector query runs, it lets the answer cite something a human can open, and it gives you a way to expire content without rebuilding the world.
Permissions that travel with the passage
Entitlements belong on the passage rather than only on the index, so that a reindex cannot silently widen access. The section below covers the enforcement mechanics.
Provenance and citation
Provenance records which source, version and passage contributed to each answer. Without it nobody can audit a response or demonstrate that the system used evidence the user was entitled to see.
Capture it at generation time, because reconstructing it afterwards from logs is guesswork dressed up as evidence. In regulated work this is the difference between a system that clears review and one that stalls in it.
Deletion and data removal
When a document is deleted or a customer exercises a deletion right, the passages derived from that document have to disappear from the vector store, the keyword index, the cache and any derived summaries. Design the deletion path on day one. Retrofitting it into a live index is one of the more unpleasant pieces of work in this field.
FAQs
What does a RAG system cost to run?
Costs land in three places. Indexing is a one-off per document plus a recurring cost for updates, and it scales with corpus size and refresh frequency. Retrieval is a small cost per query, usually dominated by the vector store rather than the model.
Generation is the largest line and scales with the number of tokens you place in the context window, which is the reason precision in retrieval pays for itself twice, once in accuracy and once on the invoice.
What roles do we need on a RAG team?
Can we use RAG on data we are not permitted to move?
Often yes. Retrieval can run against an index held inside the same boundary as the source, with only the retrieved passages crossing into the model call, and models can be invoked inside a private network so no content leaves.
The design questions become where the index physically lives, which jurisdiction it sits in, and what is written to logs, because prompt and completion logging is where residency commitments quietly break.
How do we handle documents that contradict each other?
Does RAG work on spreadsheets, tables and scanned PDFs?
Each needs its own treatment. Tables lose their meaning when flattened into prose, so keep the structure and consider answering table questions with generated queries rather than retrieval.
Scanned documents need OCR quality good enough that the text is worth indexing, and the OCR error rate becomes a ceiling on retrieval accuracy. Budget for document processing as a workstream in its own right, because it is routinely underestimated.
Who owns the RAG index once the system is live?
How do we know when to stop tuning retrieval and ship?
When recall at k has plateaued across two or three consecutive changes and the remaining errors in your evaluation set are dominated by ambiguous questions rather than missed passages. That plateau is the honest signal that further retrieval work has low marginal value, and effort should move to generation, interface design and the review path for flagged answers.
Written by
Ammar Nizami
Senior Forward-Deployed Engineer, Data Engineering practice

Let's deliver
Bring us the process. We will bring the authority model.
The agent-native AWS modernization firm. Data platforms moved. Legacy retired. AI agents in production. AWS Premier Tier Services Partner since 2026, on AWS since 2008.